Qwen models
43 models on Infery.ai.
Qwen2.5 7B Instruct Turbo
qwen2.5-7b-instruct
Qwen2.5 7B is the latest series of Qwen large language models. 32,768 token context window, maximum output of 32,768 tokens.
33K ctx
Qwen2.5 VL 72B Instruct
qwen2.5-vl-72b-instruct
Qwen2.5-VL is proficient in recognizing common objects such as flowers, birds, fish, and insects. 128,000 token context window.
32K ctx
Qwen3 14B
qwen3-14b
Qwen3-14B is a dense 14.8B parameter causal language model from the Qwen3 series, designed for both complex reasoning and efficient…
41K ctx
Qwen3 235B A22B
qwen3-235b-a22b
Qwen3-235B-A22B is a 235B parameter mixture-of-experts (MoE) model developed by Qwen, activating 22B parameters per forward pass.
131K ctx
Qwen3 235B A22B Instruct 2507
qwen3-235b-a22b-2507
Qwen3-235B-A22B-Instruct-2507 is a multilingual, instruction-tuned mixture-of-experts language model based on the Qwen3-235B architecture…
262K ctx
Qwen3 235B A22B Thinking 2507
qwen3-235b-a22b-thinking-2507
Qwen3-235B-A22B-Thinking-2507 is a high-performance, open-weight Mixture-of-Experts (MoE) language model optimized for complex reasoning…
131K ctx
Qwen3 30B A3B
qwen3-30b-a3b
Qwen3, the latest generation in the Qwen large language model series, features both dense and mixture-of-experts (MoE) architectures to…
41K ctx
Qwen3 30B A3B Instruct 2507
qwen3-30b-a3b-instruct-2507
Qwen3-30B-A3B-Instruct-2507 is a 30.5B-parameter mixture-of-experts language model from Qwen, with 3.3B active parameters per inference.
262K ctx
Qwen3 30B A3B Thinking 2507
qwen3-30b-a3b-thinking-2507
Qwen3-30B-A3B-Thinking-2507 is a 30B parameter Mixture-of-Experts reasoning model optimized for complex tasks requiring extended multi-step…
131K ctx
Qwen3 32B
qwen3-32b
Qwen3-32B is a dense 32.8B parameter causal language model from the Qwen3 series, optimized for both complex reasoning and efficient…
41K ctx
Qwen3.5-122B-A10B
qwen3.5-122b-a10b
The Qwen3.5 122B-A10B native vision-language model is built on a hybrid architecture that integrates a linear attention mechanism with a…
262K ctx
Qwen3.5-27B
qwen3.5-27b
The Qwen3.5 27B native vision-language Dense model incorporates a linear attention mechanism, delivering fast response times while…
262K ctx
Qwen3.5-35B-A3B
qwen3.5-35b-a3b
The Qwen3.5 Series 35B-A3B is a native vision-language model designed with a hybrid architecture that integrates linear attention…
262K ctx
Qwen3.5 397B A17B
qwen3.5-397b-a17b
The Qwen3.5 series 397B-A17B native vision-language model is built on a hybrid architecture that integrates a linear attention mechanism…
262K ctx
Qwen3.5-9B
qwen3.5-9b
Qwen3.5-9B is a multimodal foundation model from the Qwen3.5 family, designed to deliver strong reasoning, coding, and visual understanding…
262K ctx
Qwen3.5 Plus 2026-02-15
qwen3.5-plus-02-15
The Qwen3.5 native vision-language series Plus models are built on a hybrid architecture that integrates linear attention mechanisms with…
1M ctx
Qwen3.5 Plus 2026-04-20
qwen3.5-plus-20260420
Qwen3.5 Plus (April 2026) is a large-scale multimodal language model from Alibaba.
1M ctx
Qwen3.6 27B
qwen3.6-27b
Qwen3.6 27B is a dense 27-billion-parameter language model from the Qwen Team at Alibaba, released in April 2026.
262K ctx
Qwen3.6 35B A3B
qwen3.6-35b-a3b
Qwen3.6-35B-A3B is an open-weight multimodal model from Alibaba Cloud with 35 billion total parameters and 3 billion active parameters per…
262K ctx
Qwen3.6 Max Preview
qwen3.6-max-preview
Qwen3.6-Max-Preview is a proprietary frontier model from Alibaba Cloud built on a sparse mixture-of-experts architecture with approximately…
262K ctx
Qwen3.6 Plus
qwen3.6-plus
Qwen 3.6 Plus builds on a hybrid architecture that combines efficient linear attention with sparse mixture-of-experts routing, enabling…
1M ctx
Qwen3.7 Flash
qwen3.7-flash
Qwen3.7 Flash is a vision-language reasoning model from Alibaba. 1,000,000 token context window, maximum output of 65,536 tokens.
1M ctx
Qwen3.8 2.4T A95B
qwen3.8-2.4t-a95b
Qwen3.8 2.4T A95B is an open-weight sparse mixture-of-experts model from Qwen and the open-weight variant of Qwen3.8 Max, with 95 billion…
262K ctx
Qwen3.8 27B
qwen3.8-27b
Qwen3.8 27B is an open-weight dense vision-language model from Qwen. 262,144 token context window, maximum output of 131,072 tokens.
262K ctx
Qwen3 8B
qwen3-8b
Qwen3-8B is a dense 8.2B parameter causal language model from the Qwen3 series, designed for both reasoning-heavy tasks and efficient…
41K ctx
Qwen3.8 Flash
qwen3.8-flash
Qwen3.8 Flash is a multimodal reasoning model from Alibaba. 1,000,000 token context window, maximum output of 131,072 tokens.
1M ctx
Qwen3.8 Max (0902)
qwen3.8-max-0902
Qwen3.8 Max 0902 is an updated snapshot of Qwen3.8 Max from Alibaba's Qwen team.
1M ctx
Qwen3 Coder 30B A3B Instruct
qwen3-coder-30b-a3b-instruct
Qwen3-Coder-30B-A3B-Instruct is a 30.5B parameter Mixture-of-Experts (MoE) model with 128 experts (8 active per forward pass), designed for…
160K ctx
Qwen3 Coder 480B A35B
qwen3-coder
Qwen3-Coder-480B-A35B-Instruct is a Mixture-of-Experts (MoE) code generation model developed by the Qwen team.
262K ctx
Qwen3 Coder Next
qwen3-coder-next
Qwen3-Coder-Next is an open-weight causal language model optimized for coding agents and local development workflows.
262K ctx
Qwen3 Max Thinking
qwen3-max-thinking
Qwen3-Max-Thinking is the flagship reasoning model in the Qwen3 series, designed for high-stakes cognitive tasks that require deep…
262K ctx
Qwen3 Next 80B A3B Instruct
qwen3-next-80b-a3b-instruct
Qwen3-Next-80B-A3B-Instruct is an instruction-tuned chat model in the Qwen3-Next series optimized for fast, stable responses without…
262K ctx
Qwen3 Next 80B A3B Thinking
qwen3-next-80b-a3b-thinking
Qwen3-Next-80B-A3B-Thinking is a reasoning-first chat model in the Qwen3-Next line that outputs structured “thinking” traces by default.
131K ctx
Qwen3 VL 235B A22B Instruct
qwen3-vl-235b-a22b-instruct
Qwen3-VL-235B-A22B Instruct is an open-weight multimodal model that unifies strong text generation with visual understanding across images…
262K ctx
Qwen3 VL 235B A22B Thinking
qwen3-vl-235b-a22b-thinking
Qwen3-VL-235B-A22B Thinking is a multimodal model that unifies strong text generation with visual understanding across images and video.
131K ctx
Qwen3 VL 30B A3B Instruct
qwen3-vl-30b-a3b-instruct
Qwen3-VL-30B-A3B-Instruct is a multimodal model that unifies strong text generation with visual understanding for images and videos.
131K ctx
Qwen3 VL 30B A3B Thinking
qwen3-vl-30b-a3b-thinking
Qwen3-VL-30B-A3B-Thinking is a multimodal model that unifies strong text generation with visual understanding for images and videos.
131K ctx
Qwen3 VL 32B Instruct
qwen3-vl-32b-instruct
Qwen3-VL-32B-Instruct is a large-scale multimodal vision-language model designed for high-precision understanding and reasoning across…
131K ctx
Qwen3 VL 8B Instruct
qwen3-vl-8b-instruct
Qwen3-VL-8B-Instruct is a multimodal vision-language model from the Qwen3-VL series, built for high-fidelity understanding and reasoning…
131K ctx
Qwen3 VL 8B Thinking
qwen3-vl-8b-thinking
Qwen3-VL-8B-Thinking is the reasoning-optimized variant of the Qwen3-VL-8B multimodal model, designed for advanced visual and textual…
131K ctx
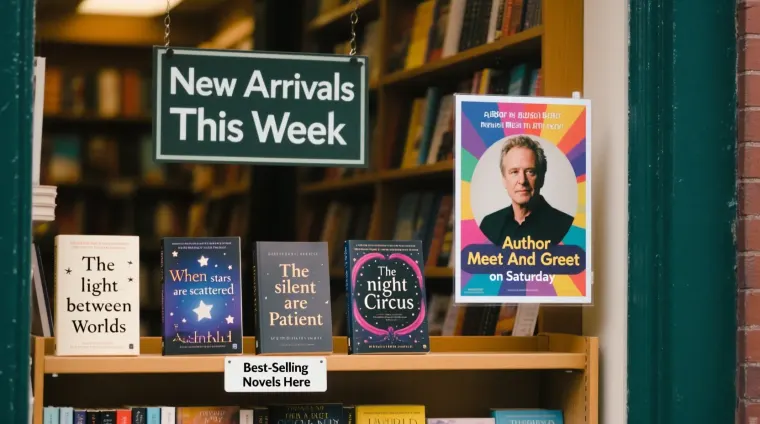
Qwen Image
qwen/qwen-image
Qwen Image open source model - fast, highly capable image generation model from Alibaba Qwen
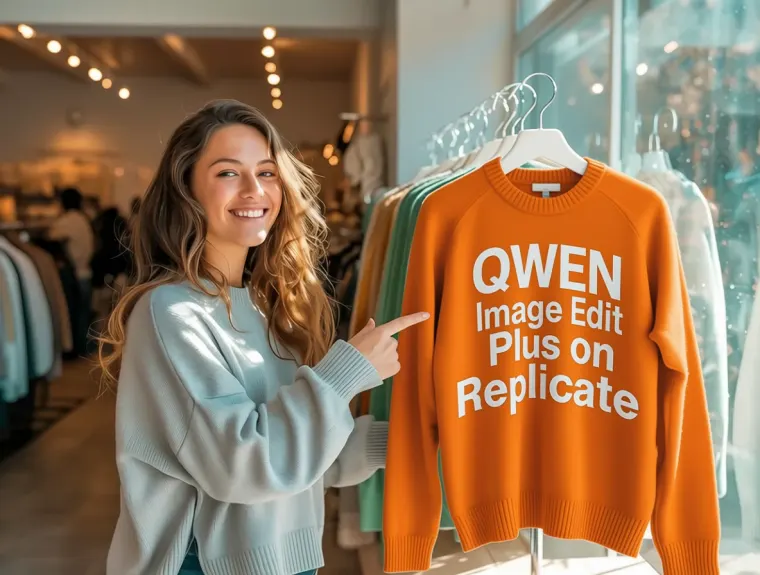
Qwen Image Edit Plus
qwen/qwen-image-edit-plus
The latest Qwen-Image’s iteration with improved multi-image editing, single-image consistency, and native support for ControlNet
Qwen Plus 0728
qwen-plus-2025-07-28
Qwen Plus 0728, based on the Qwen3 foundation model, is a 1 million context hybrid reasoning model with a balanced performance, speed, and…
1M ctx